In the rapidly evolving landscape of generative AI, a dangerous ambiguity has taken root: the conflation of "prompt engineering" with "prompt optimization." While the former implies the creative act of designing a prompt from a blank slate, the latter is the far more critical task of refining existing, functional prompts to ensure reliability, accuracy, and scalability.
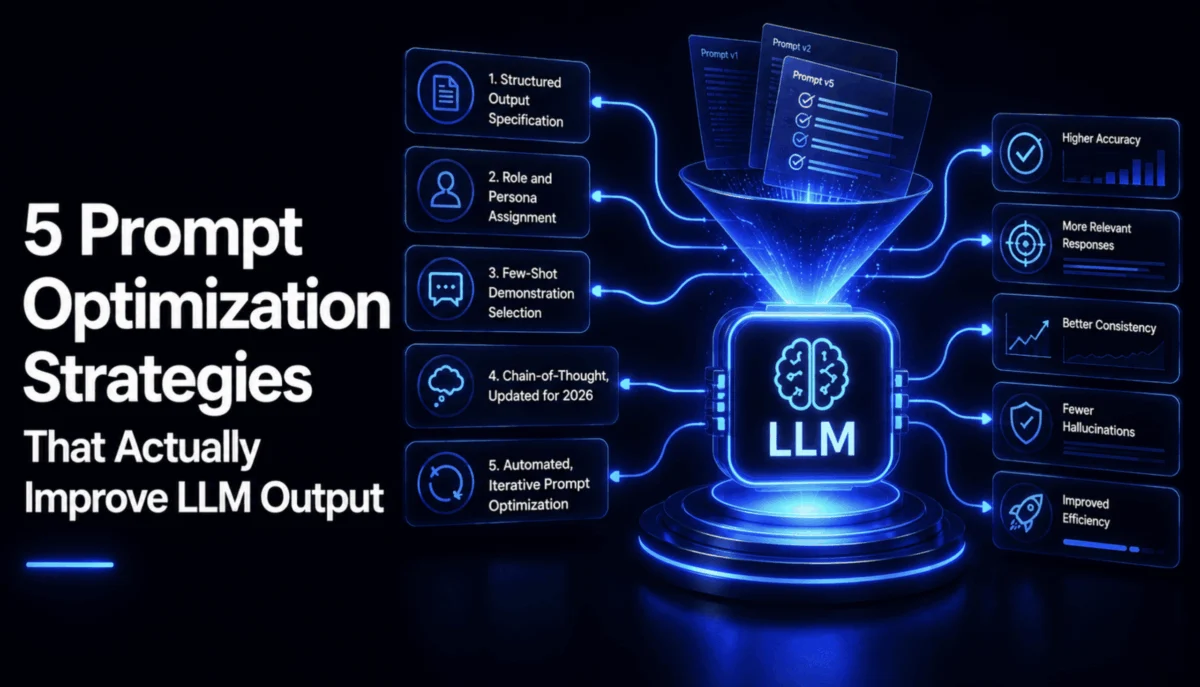
For engineers and product managers grappling with the "black box" nature of Large Language Models (LLMs), this distinction is not merely semantic. It is the difference between a prototype that works on a sunny day and a production system that fails under the pressure of real-world complexity. This article explores five proven strategies for prompt optimization—backed by data and rigorous testing—that transform LLM outputs from "plausible-sounding" prose into actionable, system-ready data.
The Anatomy of the Problem: Why Simple Prompts Fail
To understand why optimization is necessary, one must look at the "messiness" of human communication. Consider a standard meeting transcript involving three participants: Priya, Tom, and Jake. The conversation is rife with classic pitfalls: tasks are reassigned mid-sentence, complex requirements are folded into existing items, and critical responsibilities are left intentionally unresolved.
A naive prompt—such as "List the action items from this meeting"—often succeeds in producing a grammatically correct list. However, it frequently fails in three specific ways:
- Assignment Drift: It captures the initial assignee rather than the final, confirmed owner.
- Context Loss: It fails to recognize when a secondary task (like checking a tablet breakpoint) is an extension of a primary task, treating them as independent tickets.
- Hallucination of Certainty: It attempts to force an owner onto a task that was explicitly left open for triage, violating the ground truth of the transcript.
These failures are often invisible to the casual observer, appearing as clean, well-formatted text. For a downstream system, however, they represent a total failure of data integrity.
1. The Imperative of Structured Output
The first and most measurable lever in prompt optimization is moving away from natural language prose toward machine-readable schemas. In a production environment, unparseable output is not a nuisance; it is a system-level failure.
By implementing schemas—such as those defined using Pydantic in Python—developers can enforce rigid data structures. When we ask an LLM to "list action items," we receive prose. When we constrain it to a JSON schema defining owner, task, and due_date fields, we create a contract.
The optimization here is twofold:
- Validation: Using automated validation (like
model_validate_json), we can programmatically reject outputs that fail to meet our criteria, preventing bad data from entering the database. - Predictability: By defining the schema, we reduce the model’s creative leeway, forcing it to focus on the extraction task rather than the stylistic presentation of the results.
2. Role-Based Priming: Setting the Persona
Assigning a persona is more than a stylistic flourish; it is a mechanism for activating specific sub-sectors of a model’s training data. A generic prompt instructs the model to be a "helper," but a specialized prompt instructs the model to be a "meticulous executive assistant."
When the prompt is framed to emphasize the persona of an expert who understands the nuances of corporate communication—such as recognizing that assignments change and that guessing is unacceptable—the model’s internal probability distribution shifts. It becomes sensitized to the exact types of ambiguity present in the transcript. This is a low-cost, high-impact strategy that fundamentally changes how the model weights conflicting information during the inference process.
3. Few-Shot Selection: Beyond Random Examples
The concept of "few-shot" learning—providing examples within the prompt—is well-known. However, most practitioners treat it with a "more is better" mentality, adding examples haphazardly. Research suggests that the selection of examples is significantly more impactful than the sheer quantity.
To optimize, one should use diversity-aware selection. Using techniques like TF-IDF vectorization and cosine similarity, developers can identify and filter out near-duplicate examples that teach the model the same lesson repeatedly. By ensuring that the few-shot set covers distinct, challenging scenarios—such as one example with an unresolved owner, one with a reassigned task, and one with a merged requirement—the model learns to generalize across patterns rather than memorizing a single workflow.
4. Reasoning: Chain-of-Thought and the "Chain of Draft"
Chain-of-Thought (CoT) prompting—asking a model to "think step-by-step"—has been the gold standard for complex reasoning tasks. As frontier models become more sophisticated, their native reasoning capabilities have improved, but explicitly prompting for reasoning remains vital in high-stakes, ambiguous scenarios.
On the specific problem of mobile-review reassignment, a model without CoT might latch onto the first mention of an owner. By forcing a "trace" step—where the model must document the assignment process before finalizing the output—the model is effectively required to "look back" at the full history of the dialogue.
For teams concerned about the latency and cost of tokens, the "Chain of Draft" method offers an elegant compromise. By encouraging the model to use short, concise reasoning tokens (roughly five words per step), developers can achieve the same level of logical accuracy as traditional CoT while reducing token consumption by over 90%.
5. Automated Iterative Optimization
The pinnacle of prompt engineering is the transition from manual, intuition-based tuning to automated, search-based optimization. This process involves:
- Defining a Composite Score: Creating a metric that evaluates recall, owner accuracy, and a "fabrication penalty" (to discourage the model from making up items).
- Hill-Climbing Search: Generating candidate instruction fragments and testing them against a set of real-world "ground truth" examples.
- Iterative Refinement: Keeping the fragments that improve the score and discarding those that do not.
This method removes the guesswork. In tests, automated searches often find the "minimum effective fix"—the specific instruction that resolves a failure mode without introducing unnecessary complexity. It is the most robust way to ensure that your prompt remains performant as your dataset grows or changes.
Implications for the Industry
The shift toward rigorous, data-driven prompt optimization signals the maturation of AI engineering. We are moving away from the era of "prompt hacking"—where developers share magic phrases on social media—and into an era of systematic prompt lifecycle management.
The Cost of Inaccuracy
The implications of poor prompting extend far beyond simple errors. In an enterprise context, a missed action item or an incorrectly attributed task can result in stalled projects, broken code deployments, and significant loss of human capital. By adopting the strategies outlined above, organizations can mitigate these risks.
The Future of AI Integration
As LLMs become embedded in the backbone of corporate infrastructure, the "prompt" becomes a piece of code that requires the same rigor as any other software component. It must be versioned, tested, and optimized. The tools and techniques discussed here—structured outputs, persona priming, diverse few-shot sets, reasoning traces, and automated search—represent the foundational layer of this new engineering discipline.
Conclusion
The five strategies discussed—structuring output for machine readability, defining a professional persona, selecting diverse few-shot examples, employing constrained chain-of-thought reasoning, and utilizing automated iterative optimization—are not just theoretical concepts. They are the essential toolkit for any engineer building production-grade AI.
Ultimately, prompt optimization is about discipline. It is about moving from a place of guessing what "feels right" to a place of verifying what works against the cold, hard reality of your data. By treating your prompts with the same level of care and precision as your primary codebase, you ensure that your AI models don’t just speak fluently—they perform reliably.
For those looking to move beyond the blank page, the path is clear: test early, measure often, and optimize with intent.